Autoregressive token generation is notoriously slow and memory-intensive, especially when you only need a model to make a structured classification or routing decision rather than write out paragraphs of text.
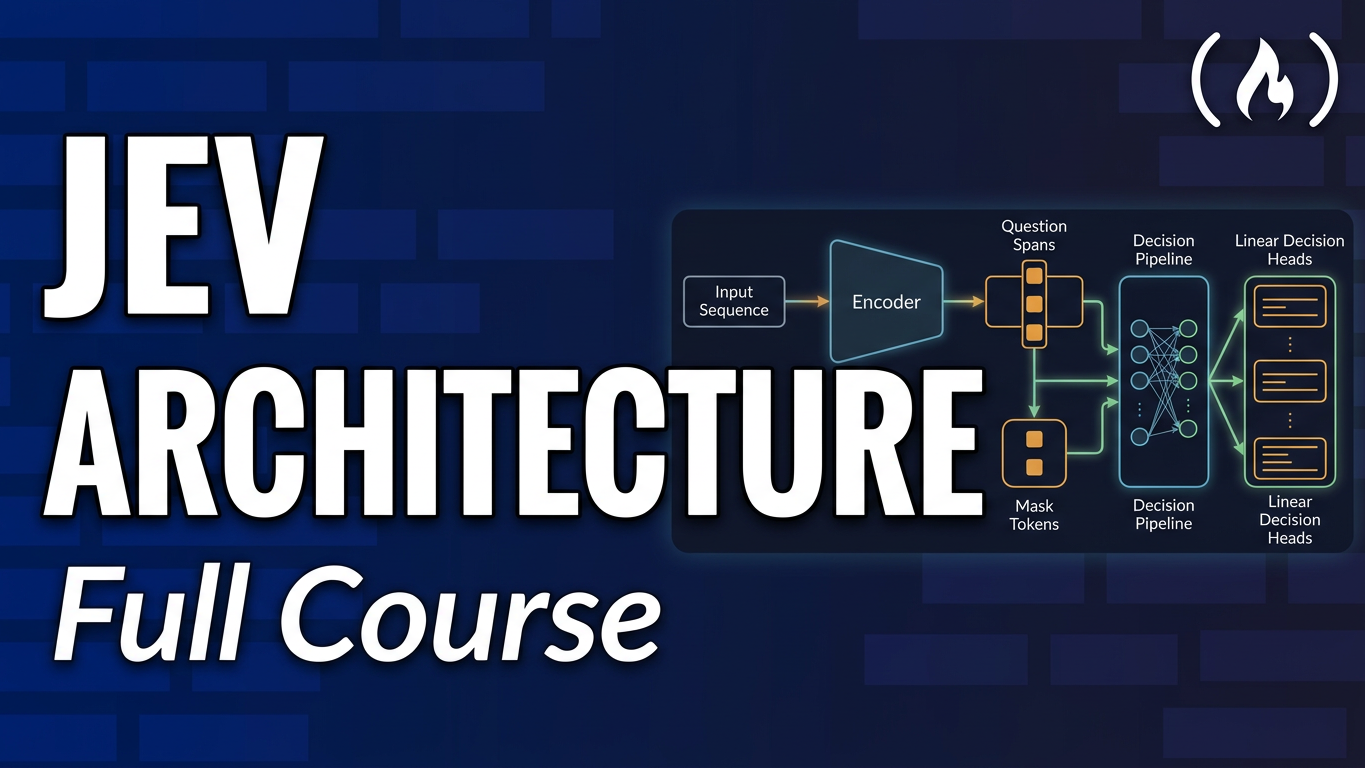
To help engineers bypass autoregressive bottlenecks, freeCodeCamp just released the Jev Course: Prefill-Only Inference and Decision Models from Scratch.
This in-depth PyTorch guide walks you through building blazing-fast, decision-oriented architectures that process inputs entirely within the initial prefill stage.
What You Will Learn
- Prefill-Only Architecture
Learn how to eliminate token-by-token decoding loops to run ultra-low latency classifications and actions directly from prompt evaluation. - Encoder and Decoder Design
Build both model variants from scratch in PyTorch to understand the mathematical trade-offs between bidirectional representations and causal flows. - Custom Causal Masking
Implement low-level attention masks that preserve directional dependencies without introducing unnecessary padding overhead. - KV-Cache Reuse Strategies
Harness key-value cache states across continuous decision pipelines to process repetitive system contexts with minimal redundant compute.
You can watch the full Jev Course: Prefill-Only Inference and Decision Models from Scratch video on YouTube to start optimizing your custom language model inference workflows (2-hour watch).


